

INFRASTRUCTURE
Local Artificial Intelligence
Most of the AI applications on the market work by calling APIs from the big tech companies. That means your data, yours and your customers', leaves your control, passes through third-party servers, and both availability and cost depend on a provider alien to your business.
There is an alternative: open-weights language models. High-quality models, trained and published openly, whose weights can be downloaded and run on your own infrastructure or on that of any hosting provider.
With these models we can develop virtual assistants for your company, retrieval (RAG) systems over your documents, classification and information extraction, text and code generation, and much more, without your data ever leaving a perimeter you control: your own server or a European cloud.
At Zentense we develop custom sovereign AI solutions: we choose the open-weights model best suited to each use case, we optimise it for the available infrastructure, we integrate it with your systems and we maintain it over time.
Open-weights models, although they don't offer the performance of the most advanced or frontier models, are currently a very solid option for most tasks.
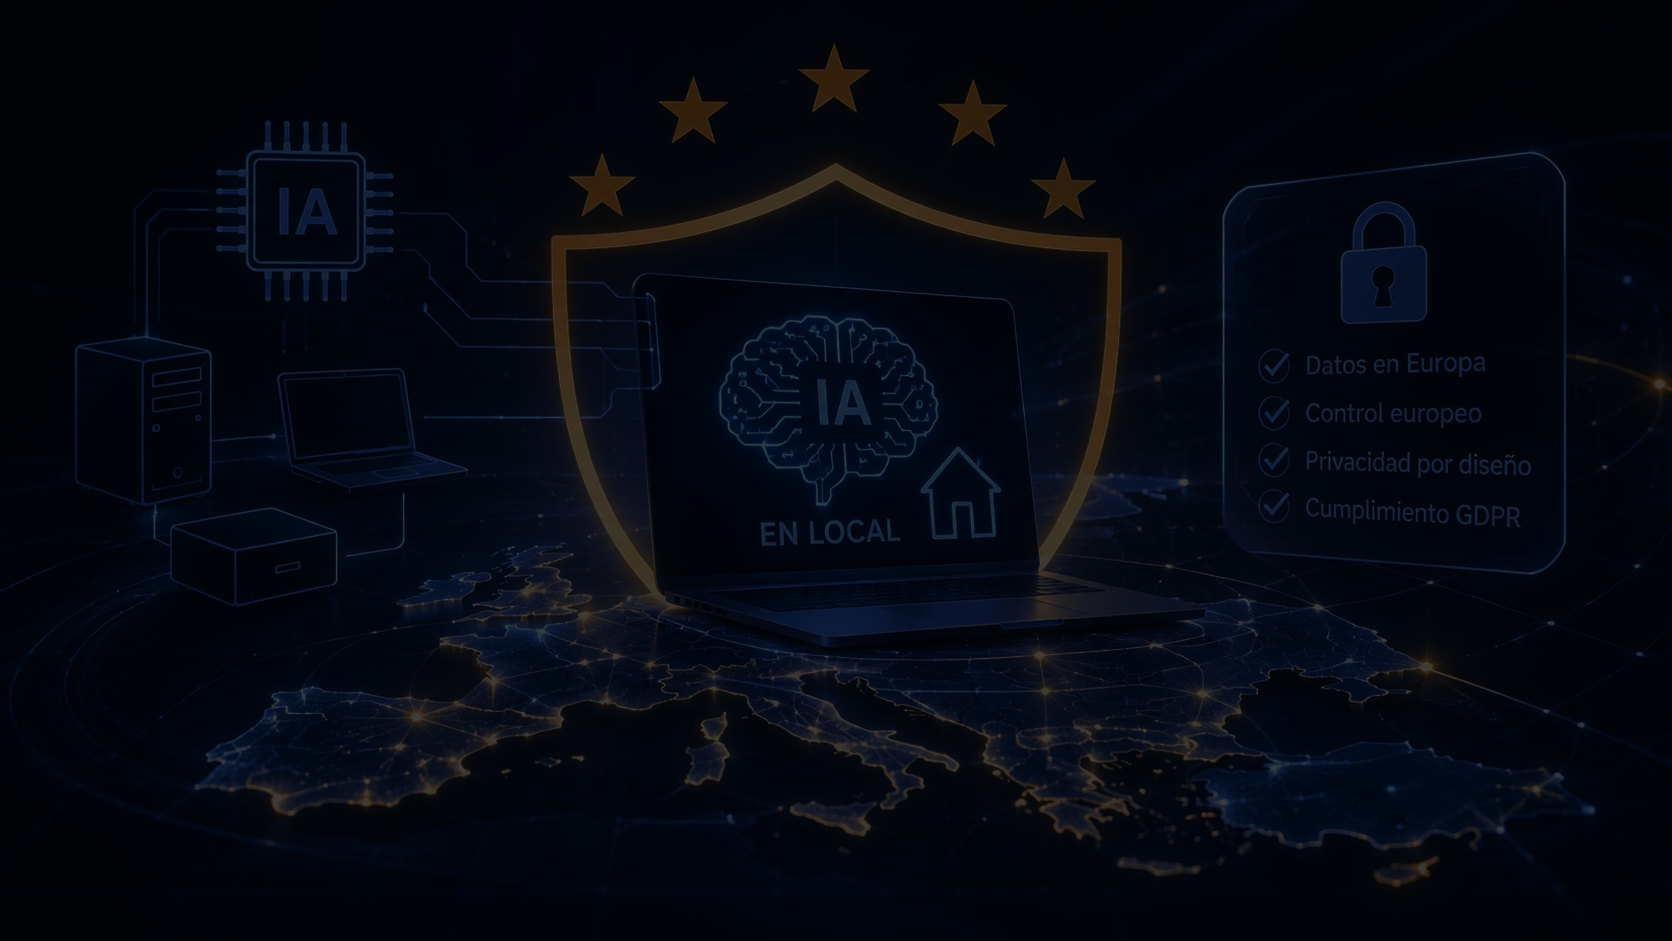
Worried about the sovereignty requirements of your industry? With AI on-premise or on a European cloud your data never leaves the EU.
Where the models run
ON-PREMISE
Running the models on your own infrastructure (GPU servers in your data center or in a colocation facility) is the most sovereign option: your data and the models never leave your control. It is the most demanding option in terms of infrastructure, but the one offering maximum security and privacy.
EUROPEAN CLOUD
Hosting the models on a European provider's cloud is a good balance between sovereignty and flexibility: your data stays in EU data centers and you comply with GDPR, without the investment of buying your own servers.
OPEN WEIGHTS
We work with high-quality open-weights models such as Mistral or Llama. Because the weights are open you can verify their behaviour, fine-tune them on your own corpus and avoid any dependence on a closed API.